Local (Ollama, LM Studio) for NinjaTrader 8 Trading: Strengths, Costs, and Best Harnesses
You can run NinjaTrader trading workflows entirely against local LLMs via Ollama or LM Studio. The model never leaves your machine; only the MCP tool calls hit the CrossTrade hosted server. For traders with proprietary strategy IP or strict data policies, this is the right pattern.
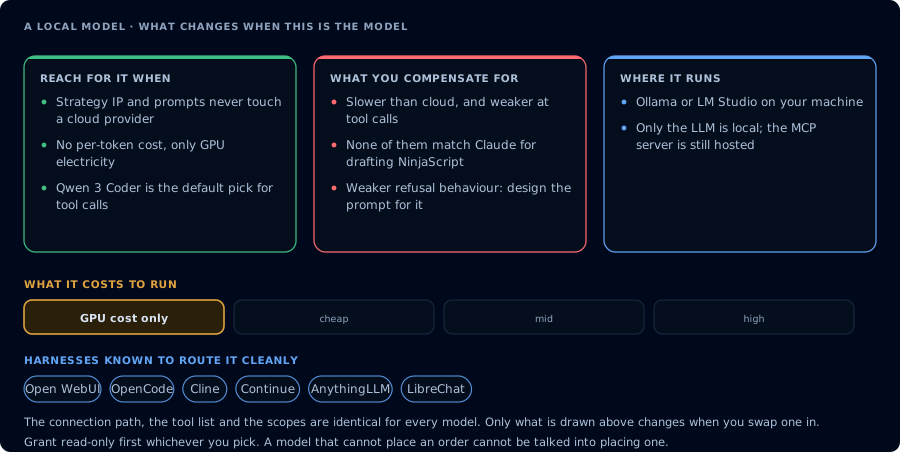
What this model changes, and what stays the same whichever one you pick.
Why local for trading
- Strategy IP stays local. Your NinjaScript and prompts never touch a cloud model provider.
- No per-token cost. GPU electricity only.
- Offline-capable for the model half; MCP calls still need internet.
Which model to pick
| Model | Strength | Notes |
|---|---|---|
| Qwen 3 Coder | Best open-weight tool-calling | Default pick |
| DeepSeek V3 / R1 (distilled) | Reasoning at low cost | R1 distilled fits on consumer GPUs |
| Llama 3.x / 4 70B | General purpose | Use 70B+ for serious MCP work |
| gpt-oss | OpenAI-style tool calling | Familiar prompts |
For NinjaScript drafting, none of the local options match Claude. Use cloud Claude for the draft, local Qwen/DeepSeek for compile-repair iterations and journal review.
Stack
Ollama (Llama / Qwen / DeepSeek / gpt-oss)
   │
   ▼
Open WebUI (or OpenCode / Cline / Continue / LibreChat / AnythingLLM)
   │  MCP
   ▼
CrossTrade hosted MCP server (https://app.crosstrade.io/v1/api/mcp)
   │
   ▼
CrossTrade NT8 Add-On in NT8
The MCP server is hosted; only the LLM is local.
Hardware floor
- 24GB VRAM (RTX 4090): Qwen 2.5 14B, DeepSeek R1 distilled, Llama 3 70B Q4.
- 48GB VRAM: Qwen 3 Coder, Llama 3 70B at higher quants.
- M-series Mac (64GB+ unified): runs most of the above acceptably.
Limitations
- Local models are slower than cloud.
- Tool-call reliability is worse than cloud Claude / GPT. Pick a tool-aware harness (the recommended list above) and a tool-tuned model (Qwen 3 Coder, DeepSeek with structured output).
- For
mcp:tradeworkflows, local models are NOT a substitute for careful prompt design. Their refusal behavior is weaker than Claude's.
Pick your harness
This model works through any MCP-capable harness. Recommended pairings: